In brief: document OCR APIs in India read Aadhaar, PAN, passport, driving licence and voter ID images and return the printed fields as structured data, replacing manual data entry at KYC checkpoints.
On this page
Manual data entry is still the default at a lot of KYC checkpoints in India — an agent looks at a scanned document and types the number, name, and date of birth into a form by hand. It’s slow, and it’s the single biggest source of KYC data-entry errors.
What document OCR actually automates
OCR (optical character recognition) for KYC documents extracts structured fields — document number, name, date of birth, address — directly from an image or scan, without a human retyping anything. Done well, it doesn’t just read text off an image; it validates the extracted fields against the expected format for that document type, catching malformed or clearly-fake documents before they even reach a verification API.
The 5 Veriqos OCR products
| API | Extracts |
|---|---|
| Aadhaar OCR API | Aadhaar number, name, DOB, address from the card image |
| PAN OCR API | PAN number, name, father’s name from the card image |
| Voter ID OCR API | EPIC number, name, address from the voter ID card |
| Passport OCR API | MRZ-derived fields — passport number, name, DOB, expiry |
| Driving Licence OCR API | DL number, name, validity, vehicle class |
Five separate products rather than one generic “document OCR” endpoint, because each document has a different layout, field set, and validation pattern — a PAN OCR call returns the fields a downstream PAN verification call expects; a passport OCR call returns the MRZ-derived fields a passport check needs.
OCR vs manual entry: the real tradeoff
Manual entry has one advantage: a human can use judgment on an ambiguous scan. Everything else favors OCR — speed (sub-second extraction vs. a manual queue), consistency (no fatigue-driven typos), and auditability (the extracted data plus the source image are both logged, so a dispute can be traced back to what was actually on the document). The tradeoff most teams actually make in practice is a hybrid: OCR-first, with manual review only on low-confidence extractions.
Where OCR fits in a full KYC pipeline
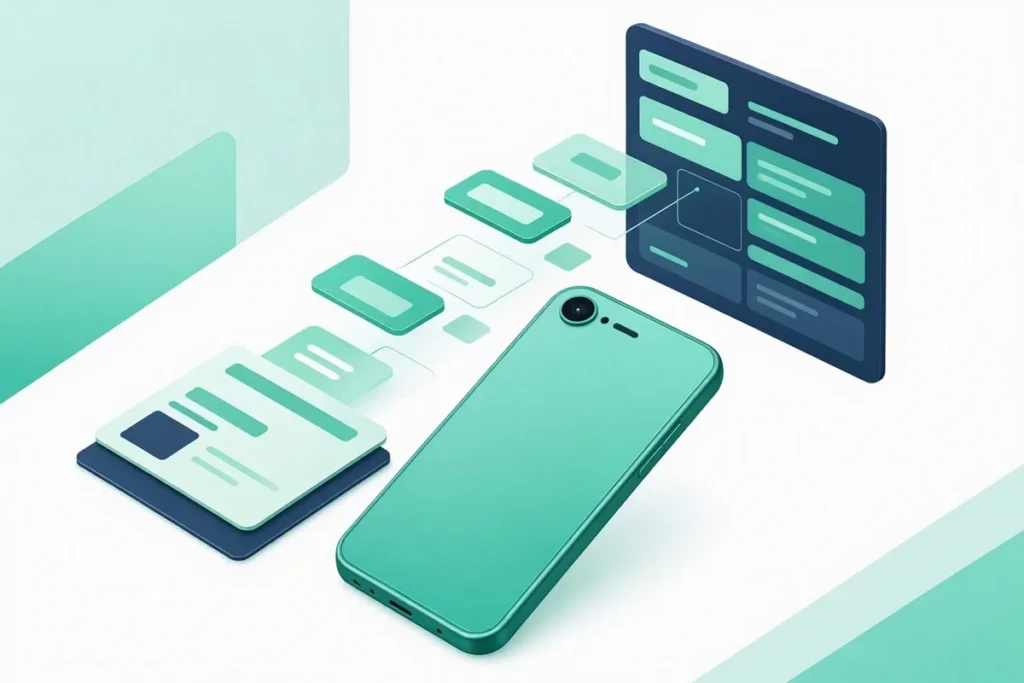
OCR is the entry point, not the whole pipeline. The typical flow: customer uploads a document photo → OCR extracts the structured fields in real time → those fields feed directly into the matching verification API (PAN Verification, Aadhaar Verification, etc.) to confirm the document is real and matches official records → the verified, structured data populates the customer’s KYC record.
Related reading
- OCR for KYC: Extracting PAN, Aadhaar & Passport Data Automatically
- KYC (Know Your Customer)
- OVD (Officially Valid Document)
Also see our KYC API Integration Checklist for a practical pre-integration reference.
Getting the most from document OCR APIs in India
Image quality decides most OCR outcomes, so guide customers through capture: a flat card, good light, all four corners in frame and no glare. Check image quality in the app before uploading, so poor images are retaken immediately rather than failing later. Treat extracted fields as data to be verified, not as verified data: pair document OCR APIs in India with a source check, such as PAN or driving licence verification, so the values you store have been confirmed against the issuing record.
For most teams, document OCR APIs in India are one step in a larger pipeline: capture, extract, confirm with the customer, then verify against the source. Treating document OCR APIs in India that way gives you both speed and data you can rely on.
More about Document OCR APIs in India
To learn more about Document OCR APIs in India, explore our Aadhaar OCR API and PAN OCR API, or talk to our team. For the official source, see the RBI’s Master Direction on KYC.